Transformer
基础
经典贝叶斯公式:
- :假设 / 隐变量(hypothesis)
- :观测数据
- :先验(prior)
- :似然(likelihood)
- :后验(posterior)
CNN
- MLP的问题:全连接数据量过大
- 数据特性:图像局部性 locality
- 平移不变性
RNN
时序问题
的选择:
- 非0: Relu
- 0 - 1: sigmoid (多个结果 softmax)
- -1 - 1: tanh
问题:
累乘,gradient 要么Exploding 要么 Vanishing -> gradient clipping
is threshold
重要的时序信息没有被区别对待 -> 根据 x 的重要程度调节 h (LSTM)
LSTM
长短期记忆
forget output input
GRU
Gated Recurrent Unit
forget老记忆:
新记忆:
最终:
Attention
seq2seq information bottleneck
QKV attention decoder hidden state
encoder hidden state
similarity
Resnet
深度模型难以训练,vanishing exploding gradient -> normalization 深度越深,能力反而下降,非overfitting -> resnet
element-wise
Shortcut connection highway networks on LSTM
效果不如resnet
维度不一致? A. zero padding B. 如果不一致则投影 C. 全部投影 选B
Deeper bottleneck architecture 没有过分 过拟合
1是reserve gradient的关键,故而 highway networks 更差()
Transformer
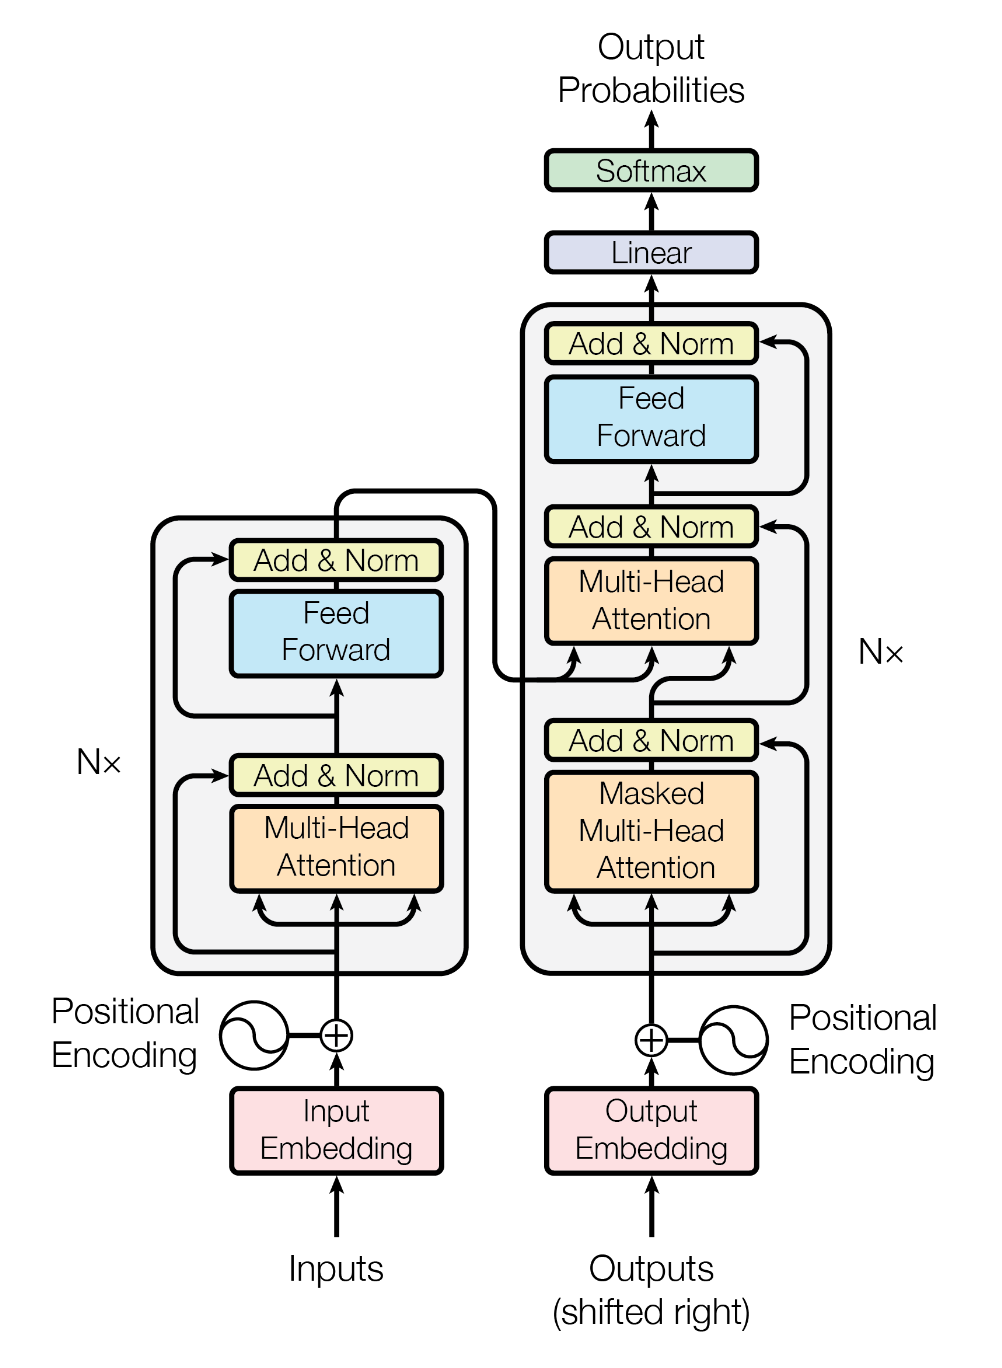 seq2seq sota: RNN - LSTM -GRU
问题:inherently sequential nature
-> parallelization
Convolutional seq2seq:
self attention 特征提取,自适应,全部上下文,计算简单
multichannel 多个kernel,不同视角
MHA: multi head
Positional Encoding
不需要计算可学参数 数值大小稳定,不光绝对位置,还有相对位置
element wise 相加真的能被识别吗? 有些head关注位置 BertViz
Decoder masked attention 设为负无穷,softmax后为0
| Layer Type | Complexity per Layer | Sequential Operations | Maximum Path Length |
|---|---|---|---|
| Self-Attention | O(n² · d) | O(1) | O(1) |
| Recurrent | O(n · d²) | O(n) | O(n) |
| Convolutional | O(k · n · d²) | O(1) | O(logₖ(n)) |
| Self-Attention (restricted) | O(r · n · d) | O(1) | O(n / r) |
Encoder-Decoder
Encoder only BERT Decoder only GPT Encoder-Decoder T5
Autoencoding models 采用 Masked Language Modeling (MLM) Objective: Reconstruction(denoising) Good use cases: • Sentiment Analysis • Named entity recognition • Word classification Example models: • BERT • ROBERTA
Autoregressive Models 采用 Causal Language Modeling (CLM) Objective: Predict Next Token Good use cases: • Text generation • Other emergent behavior • Depends on model size Example models: • GPT • BLOOM
Sequence-to-sequence models Span Corruption Objective: Reconstruct span Good use cases: • Translation • Text Summarization • Question answering Example models • T5 (Text-to-Text Transfer Transformer • BART
为什么选择 Autoregressive Models? scalable