CUDA-LeNet5
Finding performance in the details of a kernel.
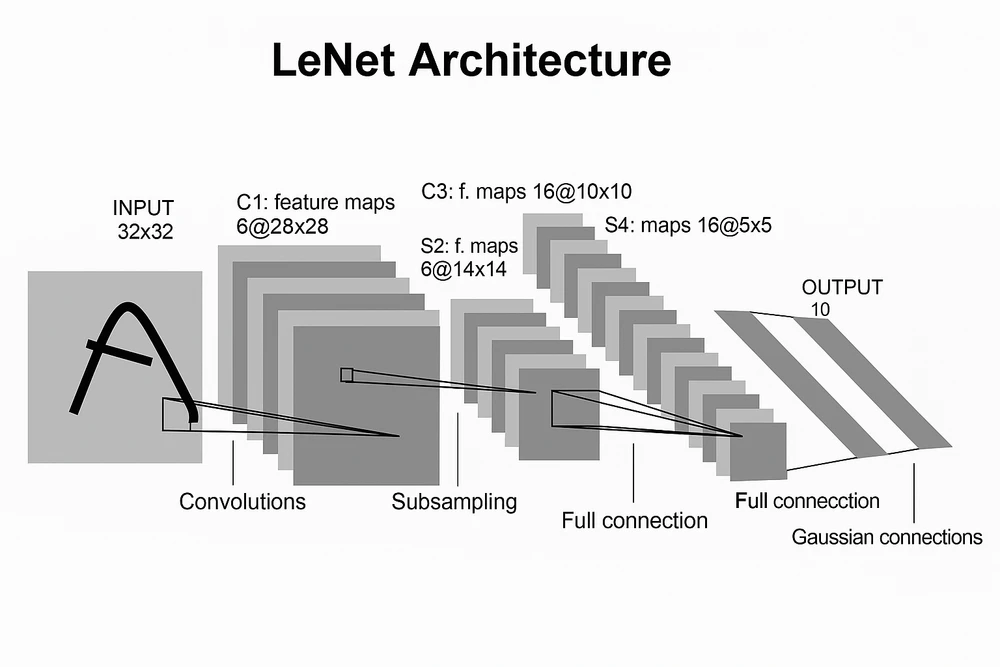
Optimised the convolution kernels with streams, Tensor Cores, shared memory and quantisation; 36% faster than an unoptimised parallel baseline (in-project tests).
Problem
Convolution performance does not depend on the number of parallel threads alone. Memory access patterns, data reuse and hardware features together decide real throughput.
Key decisions
- Memory & execution
- Used shared- and constant-memory tiling, streams and loop unrolling to cut memory traffic and scheduling overhead.
- Hardware-aware kernels
- Explored the GPU's compute capability with Tensor Cores and quantisation.
Outcome
According to the project records, 36% faster than the unoptimised parallel baseline. The result holds for the project's specified hardware, data and test setup.
Related notes (Chinese)