PACC
Seeing the cost behind distributed training.
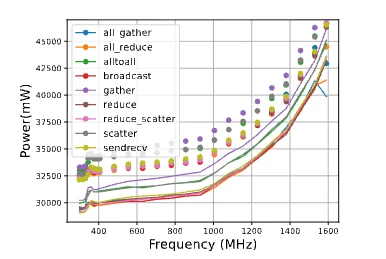
An energy-aware communication simulation framework for distributed training. Real execution traces connect GPU kernels, collective communication and system performance analysis.
Problem
Training performance cannot be judged by model size alone. Communication, kernel execution and parallel strategy together decide how efficient a system is. PACC builds a reusable analysis workflow from real workload traces to understand how these costs relate.
Key decisions
- Real execution traces
- Collected execution traces from multi-GPU distributed fine-tuning, covering FSDP and LoRA workloads.
- Two levels of visibility
- Captured both collective-communication and kernel-level execution events and converted their formats, linking model execution to the simulation tools.
- Reusable workflow
- Designed an end-to-end simulation workflow with a team of four, supporting energy and performance analysis across several mainstream models.
Outcome
We built a workflow driven by real training and inference traces. My main part was multi-GPU event capture and format conversion; the framework as a whole is a team effort.
Related notes (Chinese)